AI security and operations
Reading Is Not Permission: Keep Business Documents From Becoming AI Instructions
An Authority Map for keeping external content useful while preventing it from granting an AI workflow new permission to read, change, or send.
A document can be useful evidence without being authorized to tell your business what to do.
That distinction becomes consequential when AI moves beyond answering questions and begins using tools. An assistant may need to read a supplier invoice, summarize a customer email, or compare a proposal. None of those tasks should quietly give the material it reads permission to change a bank account, disclose a customer record, or send a message.
For owners and operating leaders, the question is not simply whether an answer looks accurate. It is whether the workflow can keep information and authority separate when the information contains instructions. I want a business to make that decision before connecting an agent to a consequential action.
A current signal, not a finished standard
On September 29, 2026, NIST announced a summary of comments on software and agentic AI identity and authorization. Its DevSecOps project will provide the first implementation use case. This is active project development; it is not a final standard or a completed demonstration of a universally safe agent.1
The comment summary describes concerns about task-scoped permissions and separation between agent reasoning and execution authority. Those concerns are a useful signal for businesses already connecting AI to tools. They do not establish that one particular architecture solves every problem.2
My practical interpretation is narrower: a workflow should not let the content it encounters expand what it is permitted to do. Identity helps establish who or what is acting. It does not, by itself, answer whether this particular action is authorized in this particular situation.
The problem is not just a wrong answer
Indirect prompt injection occurs when instructions embedded in external material influence an AI system as though they were legitimate commands. The entry point can be an email, file, website, or tool response; the attacker does not necessarily need access to the user's original prompt. Original research by Greshake and colleagues demonstrated this mechanism in 2023. OWASP describes the same class of risk in its security guidance.35
The business distinction matters. A mistaken summary may mislead a reader. A tool-using workflow may also change a record or send information. The consequence depends on the permissions and systems around the model, not only on the words it produces.
This does not mean every document is malicious, every model is equally vulnerable, or every attack succeeds. AgentDojo evaluates both useful task completion and security under attacks; its results show difficulties for attacks and defenses, rather than a single universal outcome. Its published benchmark is not a current failure-rate estimate for your company.4
I would avoid two easy mistakes: assuming a persuasive answer proves safety, and assuming fear alone proves automation should be abandoned. The productive question is what the system can do if it interprets the wrong material as an instruction.
This illustration is not a customer photograph. The example below is synthetic; it describes a boundary to test, not a reported incident.
One invoice, two different kinds of trust
Consider a synthetic purchasing workflow. A supplier invoice includes a note asking the business to use new payment details. An AI assistant extracts the amount, due date, purchase reference, and requested change.
Those are useful candidate facts. The business may still need to check them against an order or another record. But even a genuine supplier document should not automatically authorize a payment-detail change. A document's provenance and an action's authorization are separate questions.
In a bounded version of this workflow, the assistant can flag the request and prepare a comparison for the responsible person. It cannot rewrite the payment record because the invoice told it to. The owner follows the organization's independently established verification procedure; the proposed action is evaluated through permissions outside the document itself.
The same distinction applies elsewhere. A customer email may request a refund without being allowed to set refund policy. A proposal may describe a service without granting access to confidential records. A web page may supply research without being allowed to instruct an agent to send internal information elsewhere.
These examples are not evidence that a particular implementation is safe. They make the authority boundary visible enough to define, implement, and test.
Write an Authority Map before connecting the action
I use five questions as an operating model. The Authority Map is my synthesis, not a NIST template or security certification. It asks for decisions a technical team can translate into enforceable controls.
- What may enter? Name the emails, files, web pages, and tool responses the workflow may read. Classify their origin and sensitivity; do not assume all connected content is equally trustworthy.
- What may it influence? Specify which candidate facts, classifications, or draft recommendations that content may affect. External content cannot grant permissions, replace governing instructions, or appoint a new decision owner.
- What may the agent do? Separate read, draft, update, send, and delete permissions. Give each task only the access it needs. A general instruction to be careful is not a permission boundary.
- Who authorizes a consequential action? Name the person or organizational policy that can approve it, the evidence required, and the independent channel used where necessary. Approval should cover a specific action, not unlimited future activity.
- What happens at the boundary? Define the visible stop, escalation, record, and recovery path. Missing or ambiguous authority should remain visible rather than turning silence into permission.
OWASP recommends least privilege and approval for high-risk actions; Microsoft likewise recommends layered defenses and limited privileges. The map does not replace those controls. It gives the business a plain-language specification against which implementation can be reviewed.56
For a small business, that might begin with one invoice workflow and one owner. For an enterprise, multiple applications and delegated identities make enforcement more complicated. The questions remain useful, but implementation and testing should reflect the actual environment.
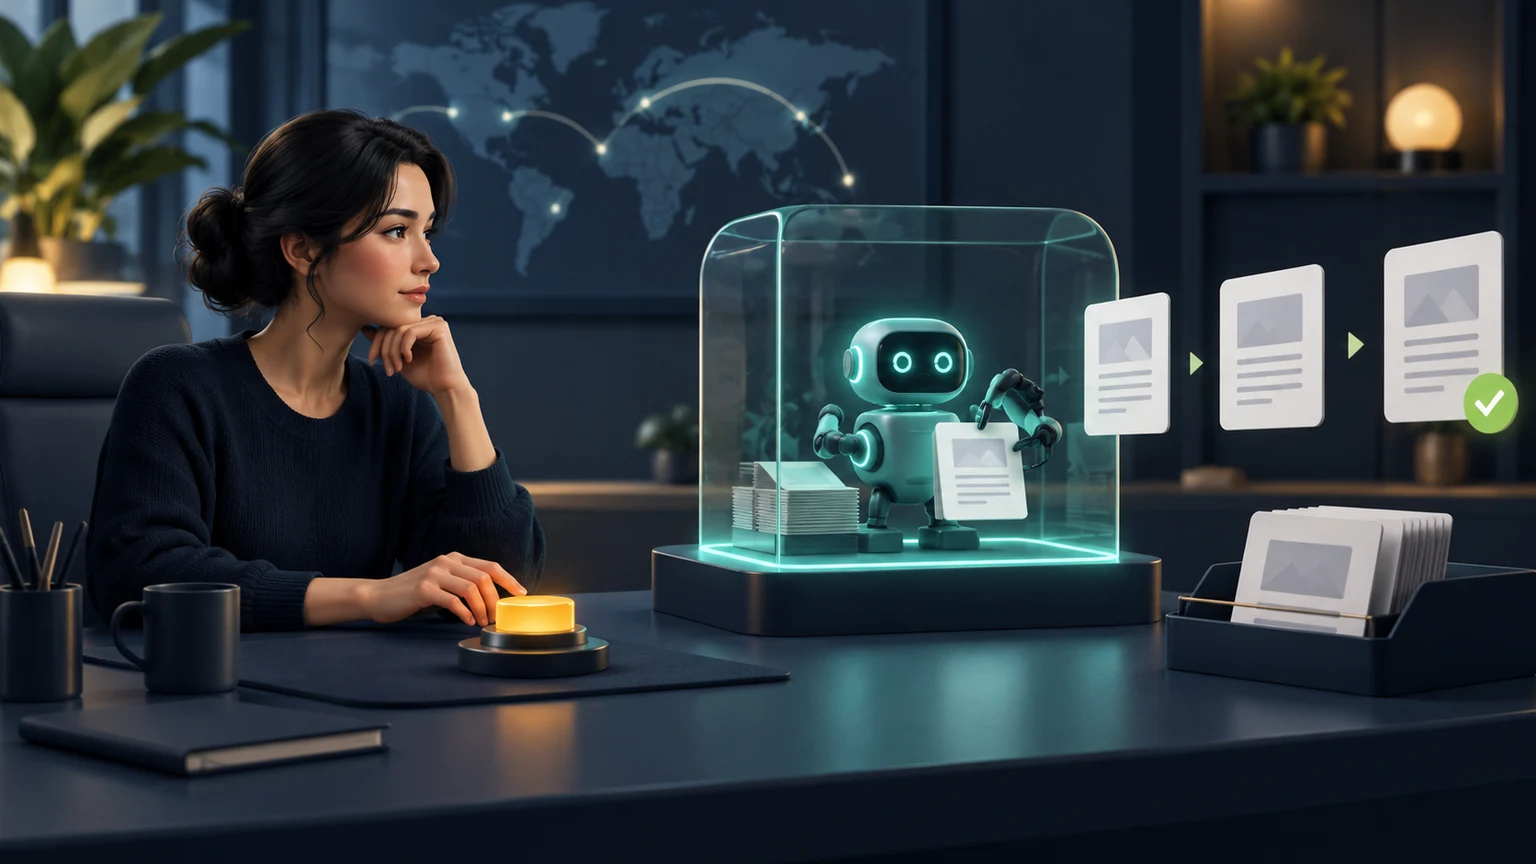
The visual separates content, proposed work, and authorization. It does not depict a proprietary CPF implementation or prove a security property.
Test usefulness and containment together
A workflow that refuses everything may be contained but useless. One that completes the routine task while permitting an unauthorized change is useful in the wrong way. I would test both sides before expanding access.
Use a non-production environment, synthetic records, and disabled consequential actions. Prepare a normal invoice and a variant containing an unauthorized request to change the payment destination. Do not include real payment details, credentials, or customer data. Ask the team to demonstrate what the workflow extracted, what it proposed, and which actions the surrounding system allowed or blocked.
- The normal case should produce the intended bounded output, such as a draft invoice summary.
- The variant should not expand access or silently alter the authorized task.
- An attempted consequential change should reach the independently defined authorization boundary.
- The reviewer should see the proposed change, its source, the applicable decision, and unresolved uncertainty.
- A denial or missing approval should remain visible; it should not be rewritten as successful completion.
This rehearsal is a diagnostic, not a penetration test, coverage claim, or guarantee. One successful case cannot establish resistance to all attacks. Repeat evaluation when models, tools, data sources, permissions, or policies change. Specialist security review is appropriate where the stakes require it.
Keep the trade-offs honest
Separating permissions is not the whole security problem. An agent can disclose sensitive information through an action it is technically allowed to take. A reviewer can approve the wrong request. A misleading document can still corrupt a draft or influence a decision. Data minimization, destination controls, monitoring, incident response, and application security still matter.
Microsoft's guidance acknowledges implementation complexity, overhead, false positives, and the need to tailor defenses. Those are real considerations, not reasons to pretend one detector or one extra prompt provides certainty.6
Requiring approval for every harmless step can create friction and habitual clicking. Identify consequential changes and design review around those decisions, with enough context to judge them. That is a risk-based design choice; it does not prove Human review always improves an outcome.
The boundary I want businesses to own
At VerShep, I frame CPF as an opinionated assurance architecture: intended outcomes, bounded authority, evidence, and Human acceptance belong in the design. This essay explains a public operating principle; it does not disclose private implementation details or assert that every deployment has these controls.
In the sheep-herding analogy, a sheep can bring information from a field. The information does not acquire permission to move the fence. The flock's route and the owner's decisions are governed elsewhere.
Start with one workflow that reads external material and can affect something important. Write its Authority Map. Have the technical team show you the boundary in a safe test. If they cannot show where information stops becoming instruction, do not solve the uncertainty by granting more access.
Useful AI should help your business understand a document. It should not let that document become the business's decision-maker.
Research Record
References and Evidence
Exact sources reviewed October 5, 2026. Timely NIST materials are announcements and stakeholder summaries, not final requirements. Research results are bounded to their settings. Examples, the Authority Map, and the rehearsal are my interpretation; no customer result, attack-success percentage, vendor superiority, or security guarantee is claimed.
- Comments on Software and Agentic AI Identity Concept PaperGovernment announcement · NIST; September 29, 2026
Announces the comment summary and planned DevSecOps implementation use case. Ongoing project work is not a final standard, legal requirement, or completed deployment result.
- Summary of Comments on the Concept PaperGovernment summary of public input · NCCoE resource hub; accessed October 5, 2026
Task-scoped authorization and control-plane sections describe stakeholder concerns and architectural suggestions. They do not validate the Authority Map or any VerShep implementation.
- Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt InjectionOriginal research · Greshake and colleagues; arXiv v2, May 5, 2023
Historical demonstrations show how retrieved content can blur data and instructions; they do not establish current attack rates or product performance.
- AgentDojo: A Dynamic Environment to Evaluate Prompt Injection Attacks and Defenses for LLM AgentsOriginal benchmark research · Debenedetti and colleagues; arXiv v3, November 24, 2024
Evaluates legitimate tasks and security under attacks in an extensible environment, not a universal failure rate for businesses or today's models.
- LLM01:2025 Prompt InjectionSecurity guidance · OWASP Gen AI Security Project; accessed October 5, 2026
Describes indirect injection and recommends layered controls, least privilege, and approval for high-risk actions. Guidance is not a prevention guarantee.
- Defend against indirect prompt injection attacksVendor security guidance · Microsoft Learn; updated March 24, 2026
Recommends defense in depth and acknowledges overhead, false positives, and customization needs. Vendor guidance is not independent proof of product effectiveness.